Azure Data Engineering Full-Stack Project
A full-stack data engineering project built on Azure, covering the path from source ingestion through processing and warehousing to the analytics layer that consumes it.
- Year
- 2024
- Engagement
- Data engineering
- Focus
- Data Engineering, DevOps
- Status
- Open source
01 — The problem
Cloud data platforms are usually learned in fragments — a pipeline here, a notebook there. What is harder, and more useful, is the joined-up path from raw source to something an analyst can query.
02 — Our solution
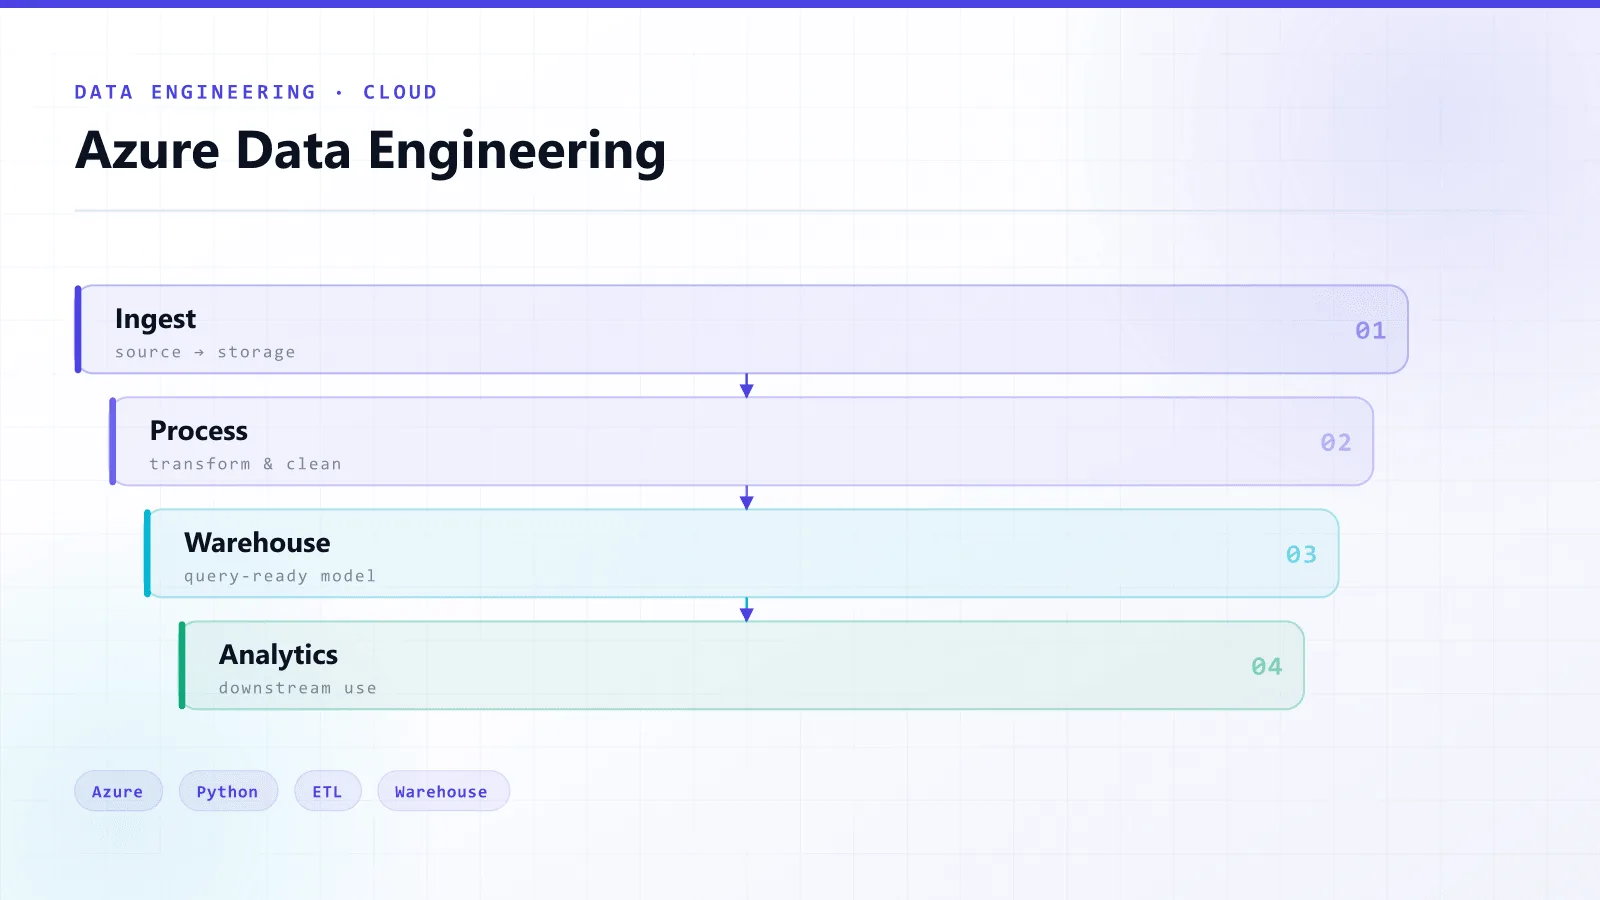
Build the whole chain on Azure: ingest from source, process and transform, land it in a warehouse layer, and expose it for analytics — so each stage's output is the next stage's contract.
How it works
The pipeline, step by step — from the first input to the final output.
- 01
Ingestion
Source data is brought into the cloud storage layer.
- 02
Processing
Transformation and cleaning stages prepare the data for modelling.
- 03
Warehouse
Processed data lands in a query-ready warehouse layer.
- 04
Analytics
The modelled data is exposed for downstream analysis.
What we built
The outcomes
01
An end-to-end Azure pipeline from source to analytics
02
Clear separation between pipeline stages
Challenges we solved
Layer boundaries
Keeping transformation logic in its own layer is what stops a cloud pipeline turning into one long, unrunnable script.
Technology stack
Want results like these?
Book a free 30-minute discovery call. We'll map out your project, recommend the right stack and send a fixed quote within 48 hours.