Voice AI Assistant
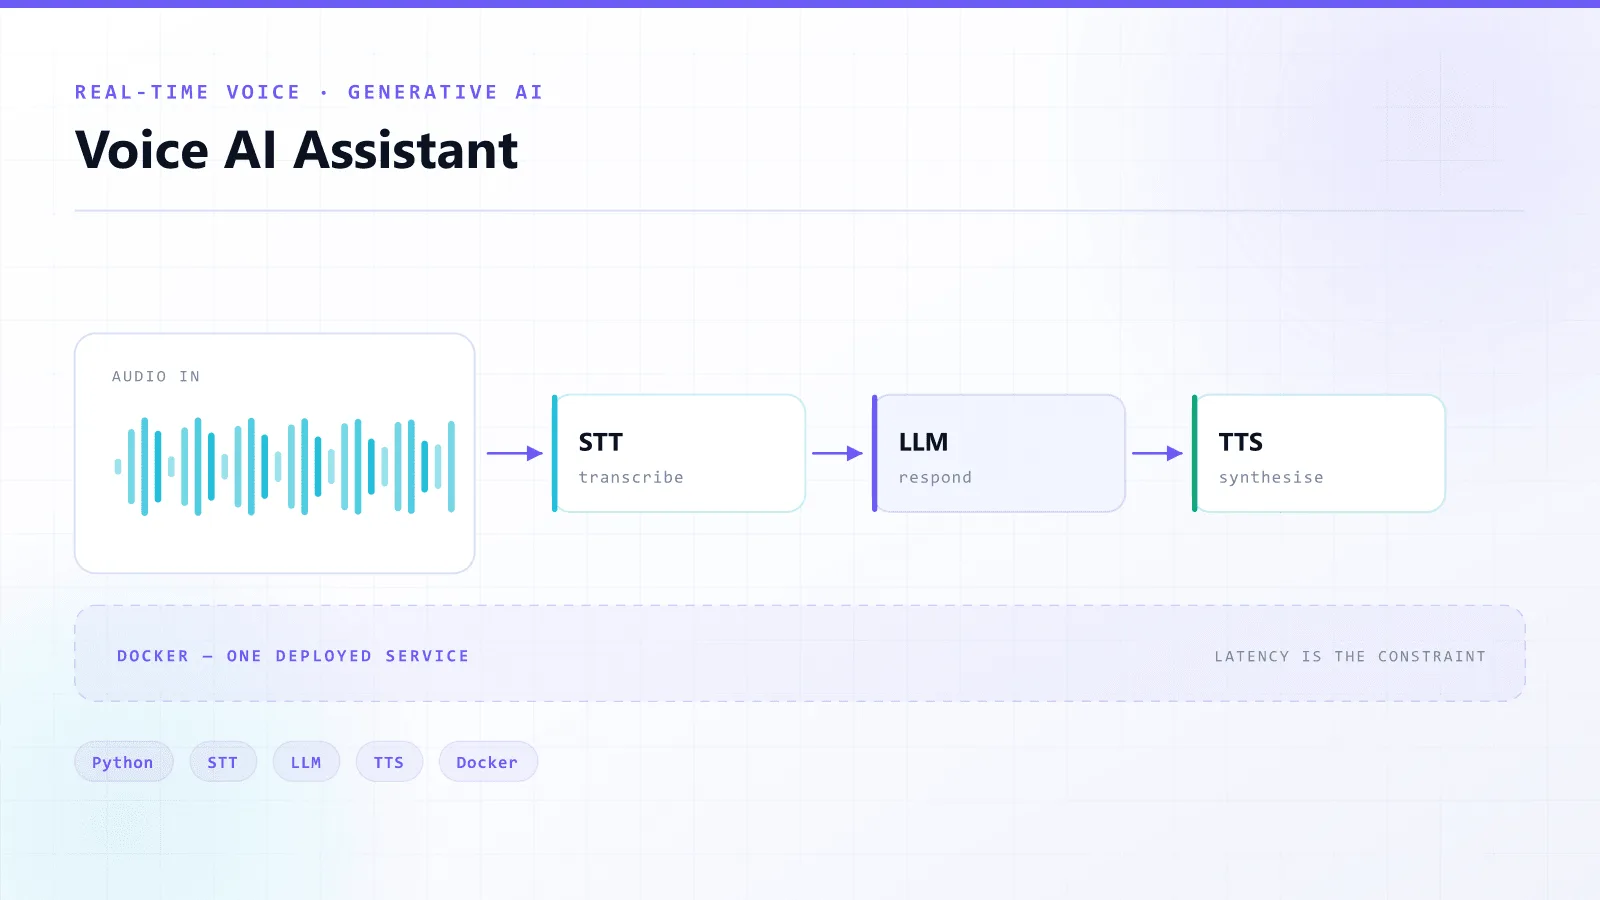
A real-time voice system integrating speech-to-text, LLM-based response generation and text-to-speech, deployed with Docker so the whole loop runs as one service.
- Year
- 2025
- Engagement
- Internal R&D build
- Focus
- Generative AI, AI/ML, DevOps
- Status
- Open source
01 — The problem
Voice assistants are three systems pretending to be one. Speech in, reasoning, speech out — and every handoff between them adds latency the user hears as an awkward pause.
02 — Our solution
Build the loop as a single deployable service. Transcription, generation and synthesis are wired together with latency treated as the primary constraint, and the whole thing is containerised so it runs the same anywhere.
How it works
The pipeline, step by step — from the first input to the final output.
- 01
Speech to text
Incoming audio is transcribed in real time.
- 02
LLM response
The transcript is answered by a language model.
- 03
Text to speech
The response is synthesised back into audio.
- 04
Containerised deployment
The full loop ships as a Docker service.
What we built
The outcomes
01
A complete voice loop running end to end
02
Deployed as one Docker service rather than three processes
Challenges we solved
Latency compounds
Three stages each adding a delay produce a conversation that feels broken. The engineering is in the seams, not the models.
Technology stack
Want results like these?
Book a free 30-minute discovery call. We'll map out your project, recommend the right stack and send a fixed quote within 48 hours.